Test. Analyze. Control. Optimize.
TACO is ioThink’s data intelligence system for manufacturing and IoT. It gives you data storage, data processing, and decision and control in a single install — and supports the full chain from algorithm development to on-site deployment.
A cloud-style data stack in one box
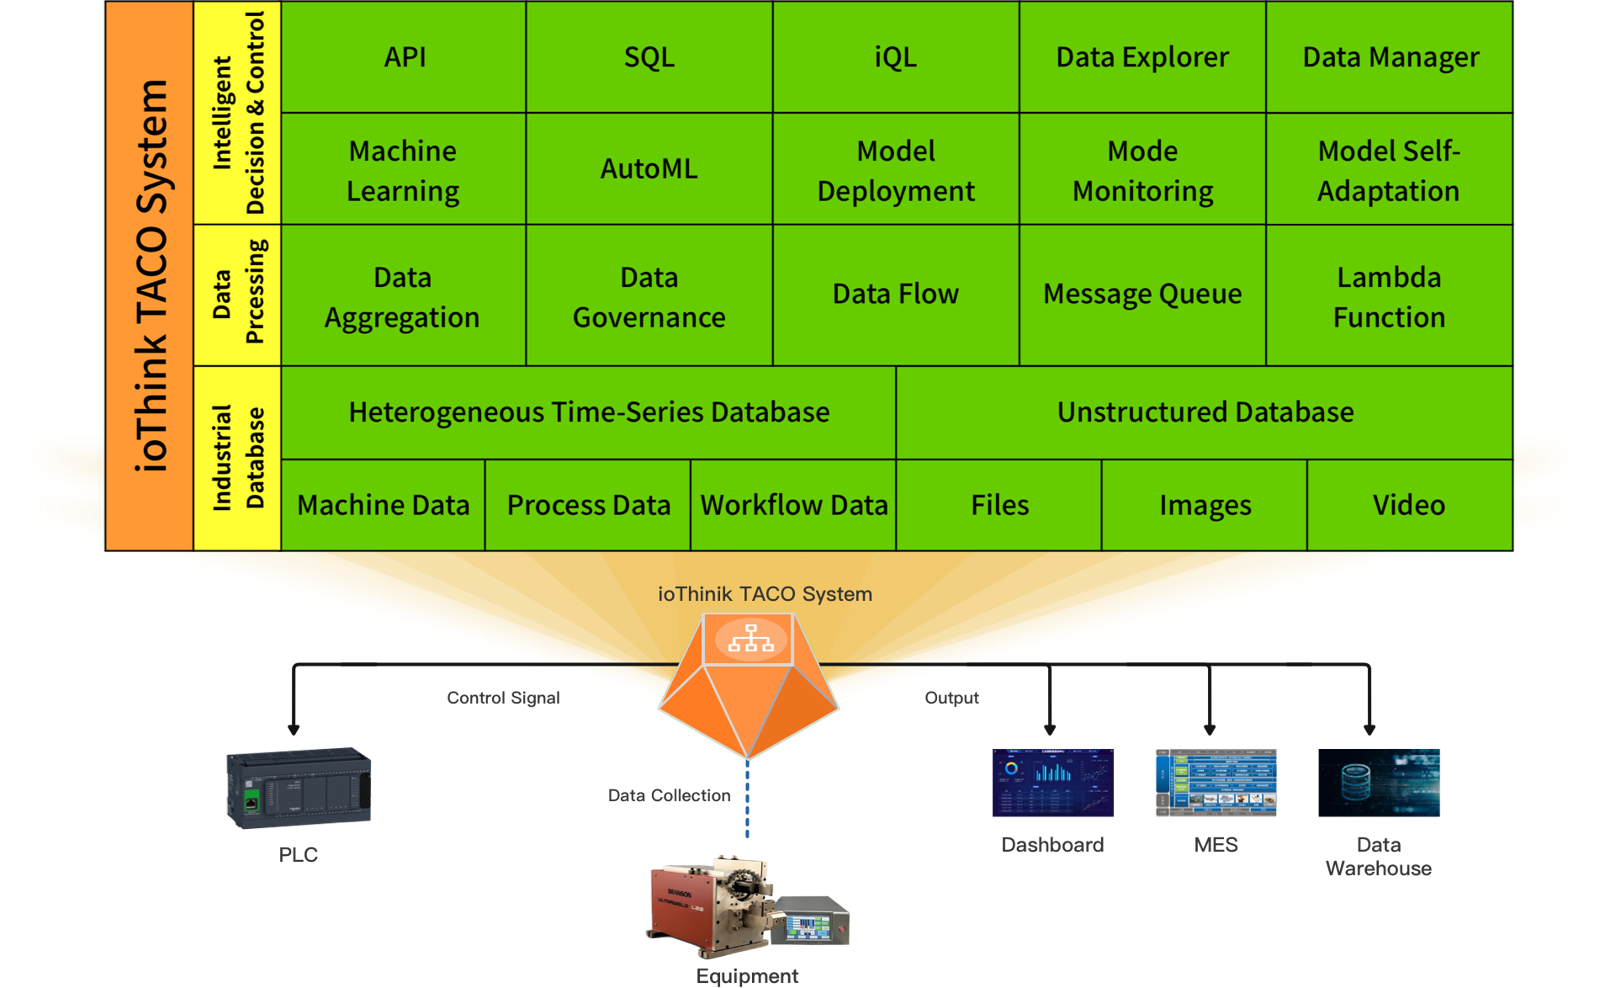
Think of TACO as some of the most useful cloud building blocks — object storage, a time-series database, lambda functions, machine learning and a message queue — packaged together and running next to your equipment.
Machine, process and workflow data flow into a heterogeneous time-series database, while files, images and video go to an unstructured store. Above that sit data processing and an intelligent decision layer that sends control signals back to PLCs and outputs to dashboards, MES and data warehouses.
Because TACO adapts quickly to new applications as a data store and machine-learning enabler, the development cycle for analytics and ML apps drops from months to weeks.
Everything between the sensor and the model
Data Collection
Manage diverse structured and unstructured data types, including device data, logs and more.
Data Cleansing
Ensure high-quality data with the consistency and structure needed for further analysis.
Data Storage
Store data efficiently and reliably, with compression and backup mechanisms built in.
Data Acceleration
Tailor data summarization to each application for faster response and lower resource use.
AI Modeling
Support ML and AI with algorithm development, model deployment and recalibration management.
Data Pipeline
Orchestrate processing workflows with message queues and machine-learning feedback loops.
Faster, smaller, cheaper to run
Data store & query
Ingest up to 50,000 records per second on a single machine, with sub-second queries across the entire history.
Extra data compression
A columnar engine shrinks storage to as little as 10% of a traditional database while meeting extensive retention needs.
Structured & unstructured
Store datasets without predefined table structures. Built-in object storage and integrated algorithms handle unstructured files.
Diverse data gathering
MQTT, HTTP, Profibus, Modbus, Kafka and more for real-time collection of time-series and event-level data.
Fast application development
The iQL query language handles flexible aggregation and analysis; Python and third-party libraries make custom ML easy to build and ship.
Low deployment cost
Runs on low-cost, general-purpose hardware and on edge Linux devices with amd64 or arm64 CPUs, such as a Raspberry Pi.
Runs wherever your data is produced
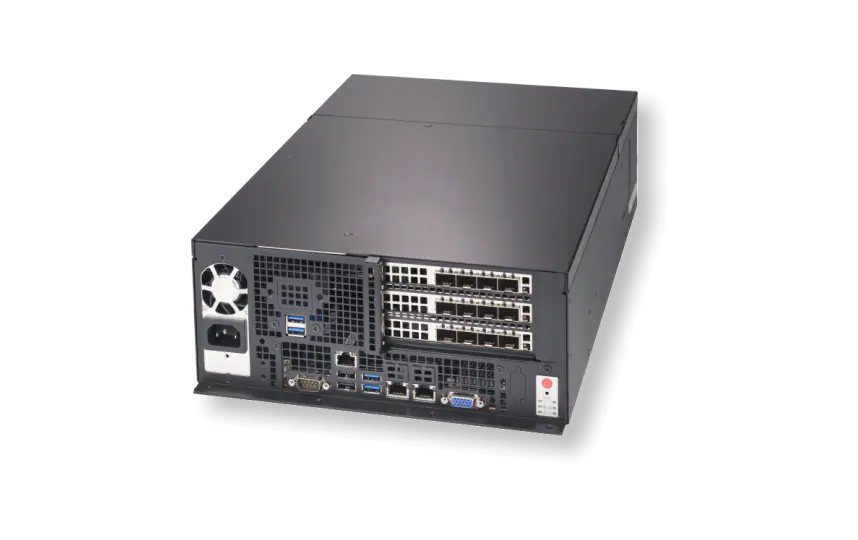
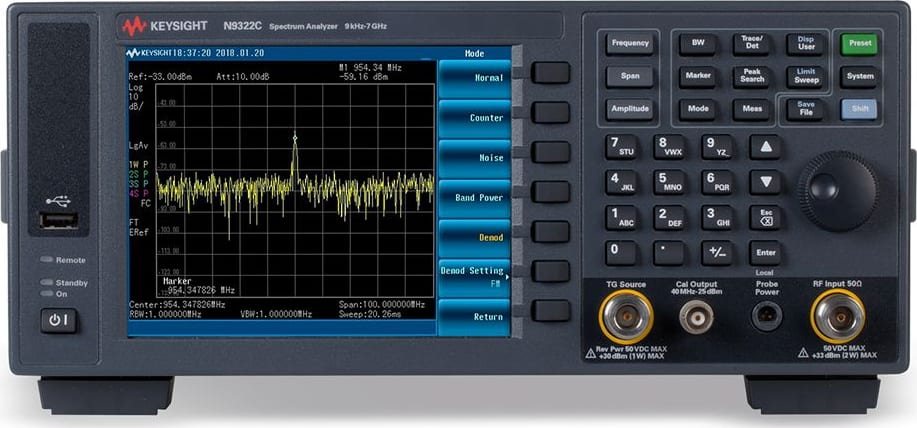
TACO installs on Linux environments on amd64 or arm64 — as software on a computer, inside an embedded system, or as a module for an advanced instrument.
Bring AI to your production line
Custom development, technology licensing or OEM products — talk to us about the partnership model that fits your equipment.